Organizations often evaluate AI by asking how accurate the model is.
That question matters, but it is incomplete. A model can perform well in testing and still create weak outcomes when the surrounding workflow has no serious capacity to verify its work.
The deeper issue is not only accuracy. It is verification capacity.
Every AI workflow creates a new review obligation. Someone—or another system—must decide whether the output is grounded, complete, appropriate, and safe enough for the next action. If the organization delegates production without budgeting for verification, it does not remove work. It hides risk inside faster output.
AI workflows need verification budgets, not only accuracy targets.
Accuracy Is a Property of a Test; Reliability Is a Property of a System
Accuracy metrics are usually produced under defined conditions. The task is bounded, the expected result is known, and performance can be compared against a reference.
Real work is less controlled.
Inputs are incomplete. Policies change. Customers describe problems ambiguously. Documents conflict. Exceptions appear. A correct answer in one context becomes a harmful answer in another.
This is why a model score cannot carry the full burden of trust. Reliability emerges from the complete system: input quality, model behavior, review design, escalation paths, ownership, and feedback.
A workflow is reliable when it can detect uncertainty, allocate review intelligently, and prevent weak output from becoming an irreversible action.
Faster Production Creates a Verification Gap
AI can increase output faster than organizations can increase judgment.
A marketing team can generate fifty campaign variations in an hour. A legal team can summarize hundreds of documents. A customer service system can draft thousands of responses. An internal agent can complete research, update records, and recommend decisions across several tools.
The visible gain is production capacity.
The hidden constraint is review capacity.
If every output receives the same manual review, the process becomes too expensive. If review is reduced indiscriminately, errors move downstream. If no one owns verification, fluent output is mistaken for dependable work.
This creates a verification gap: the distance between what AI can produce and what the organization can responsibly validate.
The more capable the production system becomes, the more important this gap becomes.
A Verification Budget Is a Strategic Allocation
A verification budget is the time, attention, tooling, and accountability reserved to evaluate AI work.
It is not a fixed amount of human checking applied to every task. It is a risk-based allocation.
Low-risk, reversible outputs may need lightweight sampling. A first draft for an internal document can be reviewed quickly because the cost of correction is low.
Medium-risk outputs may need structured checks. A customer-facing recommendation may require source validation, policy checks, and approval from a responsible owner.
High-risk or irreversible actions may require independent review, stronger evidence, and explicit human authorization. Financial decisions, legal claims, public commitments, and sensitive data actions should not inherit the same review logic as brainstorming.
The goal is not to verify everything equally. The goal is to spend verification capacity where failure has the greatest consequence.
Four Variables Should Shape the Budget
1. Consequence
What happens if the output is wrong?
Errors that affect safety, money, rights, reputation, or external commitments deserve a larger verification budget than errors in internal exploration.
2. Reversibility
Can the action be undone easily?
A draft can be revised. A published statement can be corrected, but not fully recalled. A deleted record, rejected applicant, or executed payment may be far harder to reverse.
3. Observability
Will the organization notice failure quickly?
Some errors are visible immediately. Others look plausible and remain hidden until they compound. Low-observability tasks require stronger evidence and monitoring.
4. Variability
How often does the context change?
A stable, repetitive workflow can support automated checks. A rapidly changing environment with ambiguous inputs requires more human judgment and more frequent reassessment.
Together, these variables help leaders match verification effort to real risk instead of relying on a general confidence score.
Build Verification Into the Workflow
Verification should not be added as a final inspection step after the AI system has already been designed. It should shape the workflow from the beginning.
Define the claim being verified
Different outputs require different checks. Factual accuracy, policy compliance, tone, completeness, calculation integrity, and strategic relevance are not the same quality dimension.
Teams must define what “good” means for the specific task.
Require evidence where evidence matters
When an output makes factual or analytical claims, the workflow should preserve sources, calculations, assumptions, or retrieval traces. Verification becomes much harder when the final answer is separated from the evidence that produced it.
Use layered controls
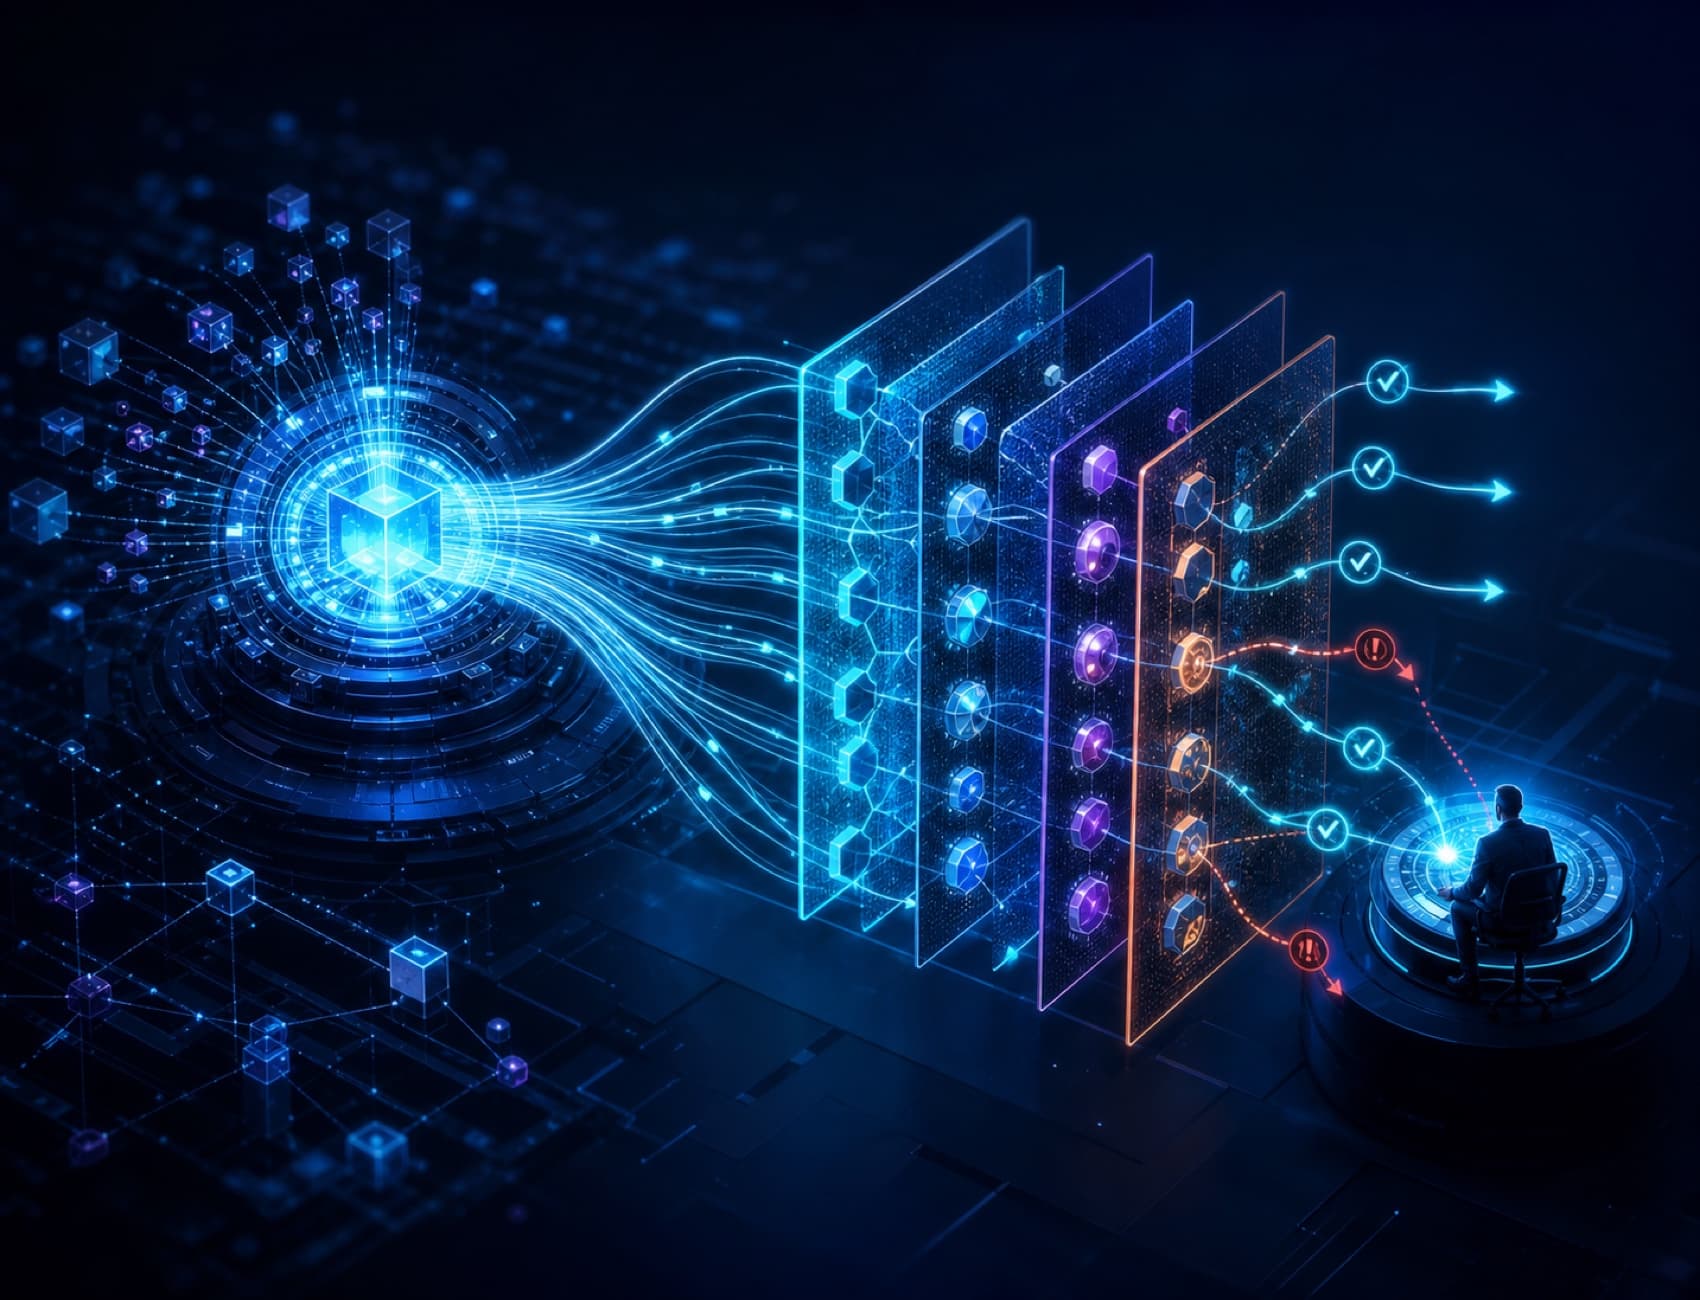
Simple rules can catch missing fields. Automated evaluators can flag inconsistency. Sampling can monitor routine work. Human experts can review ambiguous or high-consequence cases.
No single control is sufficient. Reliability comes from layers.
Design escalation before failure
The system should know when to stop, ask, defer, or transfer work. Escalation is not a sign that AI failed. It is evidence that the workflow understands its own boundaries.
Measure the review system
Teams should track not only AI error rates but also review time, escaped errors, false alarms, escalation frequency, and the kinds of failures reviewers repeatedly catch.
These measures reveal whether the verification budget is too small, poorly allocated, or focused on the wrong risks.
The Human Role Moves From Checking Everything to Governing Confidence
AI does not make human judgment less important. It changes where that judgment creates the most value.
The mature role is not to reread every sentence produced by a model. It is to design the standards, risk tiers, evidence requirements, sampling rules, and intervention points that govern the system.
This requires a different kind of capability.
Teams must learn to distinguish plausible output from supported output. Leaders must know which decisions can tolerate error and which cannot. Workflow owners must understand how failures travel downstream.
The central question becomes: how much confidence is justified, and what evidence is required before action?
Conclusion
AI adoption is often framed as a production problem: how much more work can the organization generate, automate, or accelerate?
But production is only half of the system.
The other half is the capacity to verify what deserves trust.
Organizations that scale output without scaling verification will create speed without reliability. Organizations that build risk-based verification budgets can use AI more confidently because they know where evidence, review, and human accountability still belong.
The future of AI work will not be defined only by models that answer more accurately. It will be defined by systems that know how much verification an answer deserves.
Key Takeaways
- Model accuracy does not guarantee workflow reliability.
- AI can create a verification gap when output grows faster than review capacity.
- Verification budgets should reflect consequence, reversibility, observability, and variability.
- Mature teams govern confidence through layered controls, evidence, escalation, and accountable ownership.
FAQ
What is a verification budget in an AI workflow?
It is the time, attention, tools, and accountability reserved to validate AI output in proportion to the risk of the task.
Does every AI output need human review?
No. Low-risk work can use automated checks and sampling, while high-risk or irreversible actions need stronger human oversight.
How is verification different from AI evaluation?
Evaluation measures performance under defined conditions. Verification decides whether a specific output is sufficiently supported and appropriate for real-world action.