Many teams treat AI failure as something to fix and forget.
A prompt produces a weak answer, so someone rewrites it. An automation breaks, so someone patches it. A chatbot gives the wrong response, so someone corrects the rule. A workflow creates confusion, so someone adds another approval step.
These reactions are necessary, but they are incomplete.
If every failure is handled only as an isolated error, the organization does not become smarter. It only becomes busier.
AI systems need failure memory, not only error handling.
Error Handling Solves the Moment
Error handling is about immediate recovery.
Something went wrong. The team identifies the issue, restores the workflow, corrects the output, and tries to prevent the same disruption from happening again.
This is important. AI systems that cannot recover from errors are fragile. Teams need guardrails, fallback processes, review steps, and escalation rules.
But error handling usually focuses on the incident itself.
It asks: What broke? Who fixes it? How do we resume normal operation?
Those are useful questions, but they do not capture the deeper learning. They do not always ask why the system was vulnerable, what assumption failed, what context was missing, or what pattern is beginning to repeat.
That is where failure memory becomes necessary.
Failure Memory Turns Mistakes Into System Learning
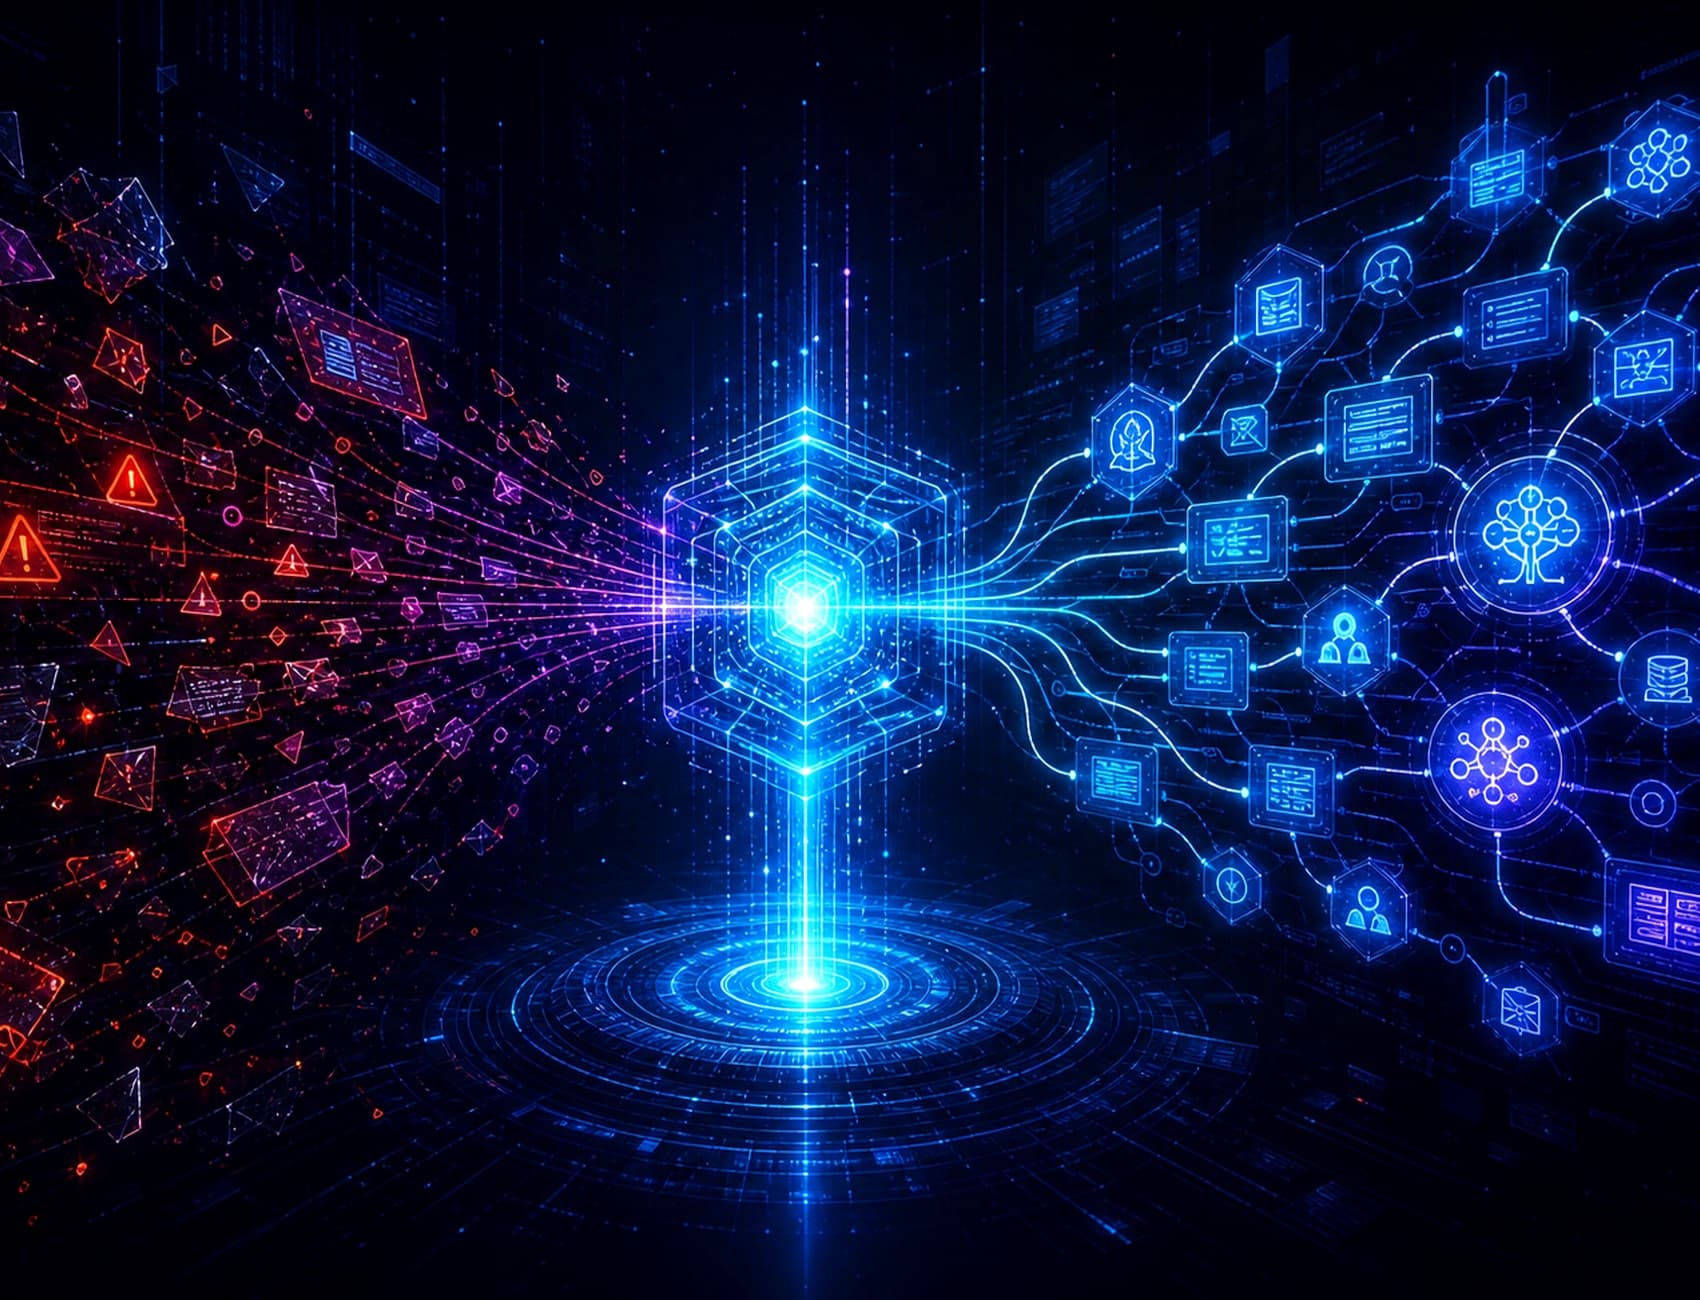
Failure memory is the practice of capturing AI failures in a way that helps future decisions, workflows, prompts, policies, and training improve.
It is not a blame log.
It is not a folder of screenshots.
It is a structured memory of what the system learned when reality disagreed with expectation.
A useful failure memory records:
- what the AI system was expected to do;
- what actually happened;
- what context was missing;
- what assumption failed;
- what human review caught or missed;
- what rule, prompt, workflow, or standard should change.
This turns failure from embarrassment into infrastructure.
Why AI Makes Failure Memory More Important
AI failures are often subtle.
A traditional software error may stop the process clearly. An AI error may look fluent, confident, and almost correct. It may produce an answer that sounds reasonable but misses context, overgeneralizes, invents details, or chooses the wrong standard.
This makes AI failures harder to see and easier to repeat.
If the team does not capture the pattern, the same weakness comes back in different forms. The prompt changes, the model changes, the user changes, but the underlying failure remains.
For example, the real problem may not be the prompt. It may be that the workflow does not define what good judgment looks like. Or that the knowledge base contains outdated assumptions. Or that the human reviewer does not have enough context to challenge the output.
Failure memory helps the organization see the system behind the incident.
The Difference Between a Bug and a Learning Signal
Not every AI failure should be treated like a technical bug.
Some failures are learning signals.
A hallucinated fact may signal that retrieval boundaries are weak. A generic strategic recommendation may signal that the system lacks customer context. A risky automation may signal that decision rights are unclear. A poor summary may signal that the source document was not structured well enough for machine use.
When teams treat these only as bugs, they fix the surface.
When they treat them as learning signals, they improve the operating system around AI.
This is the difference between technical maintenance and organizational maturity.
What a Failure Memory System Looks Like
A practical failure memory system does not need to be complicated.
It can begin with a shared register for AI incidents and near misses. Each entry should be short, structured, and connected to a decision.
The team should review patterns regularly. Which failures repeat? Which use cases create the most risk? Which workflows need clearer human checkpoints? Which examples should become training data? Which prompts or policies need revision?
The point is not to document everything forever.
The point is to prevent the organization from learning the same lesson five times.
Human Judgment Owns the Meaning of Failure
AI can help detect patterns, but humans must interpret what the failure means.
A failed output is not only a technical event. It may reveal a weak strategy, unclear standard, bad data, poor delegation, or unrealistic expectation.
This is why failure memory should not belong only to the technical team.
Leaders, domain experts, operators, and reviewers should participate. Each group sees a different part of the system.
The more important the AI workflow, the more important this shared interpretation becomes.
Final Thought
AI adoption will not mature because every system becomes perfect.
It will mature because organizations learn faster from imperfection.
Error handling helps a team recover.
Failure memory helps a team evolve.
The strongest AI systems will not be the ones that never fail. They will be the ones whose failures are captured, understood, and converted into better judgment, better workflows, and better organizational memory.
Key Takeaways
- Error Handling can be useful, but it becomes limited when it is not connected to failure memory.
- The deeper advantage comes from clearer standards, stronger judgment, and a more intentional operating system.
- Teams should treat this as a practical capability, not only an abstract idea.
FAQ
Why does failure memory matter?
Failure Memory matters because it helps teams move beyond surface activity and build a more durable system for judgment, execution, and trust.
Why is error handling not enough?
Error Handling may improve visible activity, but it does not automatically solve the deeper problem of clarity, accountability, and long-term capability.
How should teams apply this idea?
They should define the standard behind the work, review where the current system breaks down, and turn the insight into a repeatable practice.