Many teams try to improve AI performance by asking for better outputs.
That is understandable. Better outputs feel like the obvious goal. If the model answers more accurately, writes more clearly, summarizes more cleanly, or recommends more intelligently, the system appears to improve.
But operational AI does not fail only because the output is weak.
It often fails because the organization has not defined what level of confidence is required before action is allowed.
This distinction matters. In real workflows, AI is rarely valuable as a standalone answer machine. It becomes valuable when it helps people decide, prioritize, create, review, diagnose, and act. That means the system must know when an output is strong enough, when it is uncertain, and when it should be escalated to human judgment.
Without confidence thresholds, even a capable AI system can create risk at scale.
The misconception: better output solves the reliability problem
The common assumption is simple: if AI produces better answers, the workflow becomes more reliable.
This is partly true, but incomplete.
A better model can reduce errors. Better prompts can improve structure. Better retrieval can add context. Better examples can improve consistency.
But none of these automatically answer a more important operational question:
When is the output good enough to trust?
That question cannot be solved by the model alone. It requires a standard outside the model.
For low-risk work, a rough answer may be enough. For customer communication, a draft may require review. For financial, legal, medical, strategic, or brand-sensitive decisions, confidence must be treated differently.
The issue is not whether AI can produce useful work. The issue is whether the organization knows how to classify that work before it moves forward.
The deeper issue is decision permission
Every AI workflow carries an implicit question: what is the system allowed to do?
Can it draft?
Can it recommend?
Can it rank options?
Can it send?
Can it approve?
Can it reject?
Can it change a customer record, trigger an automation, modify a campaign, or influence a strategic decision?
These are not technical questions only. They are governance questions. They define the boundary between machine assistance and human accountability.
Confidence thresholds make that boundary explicit.
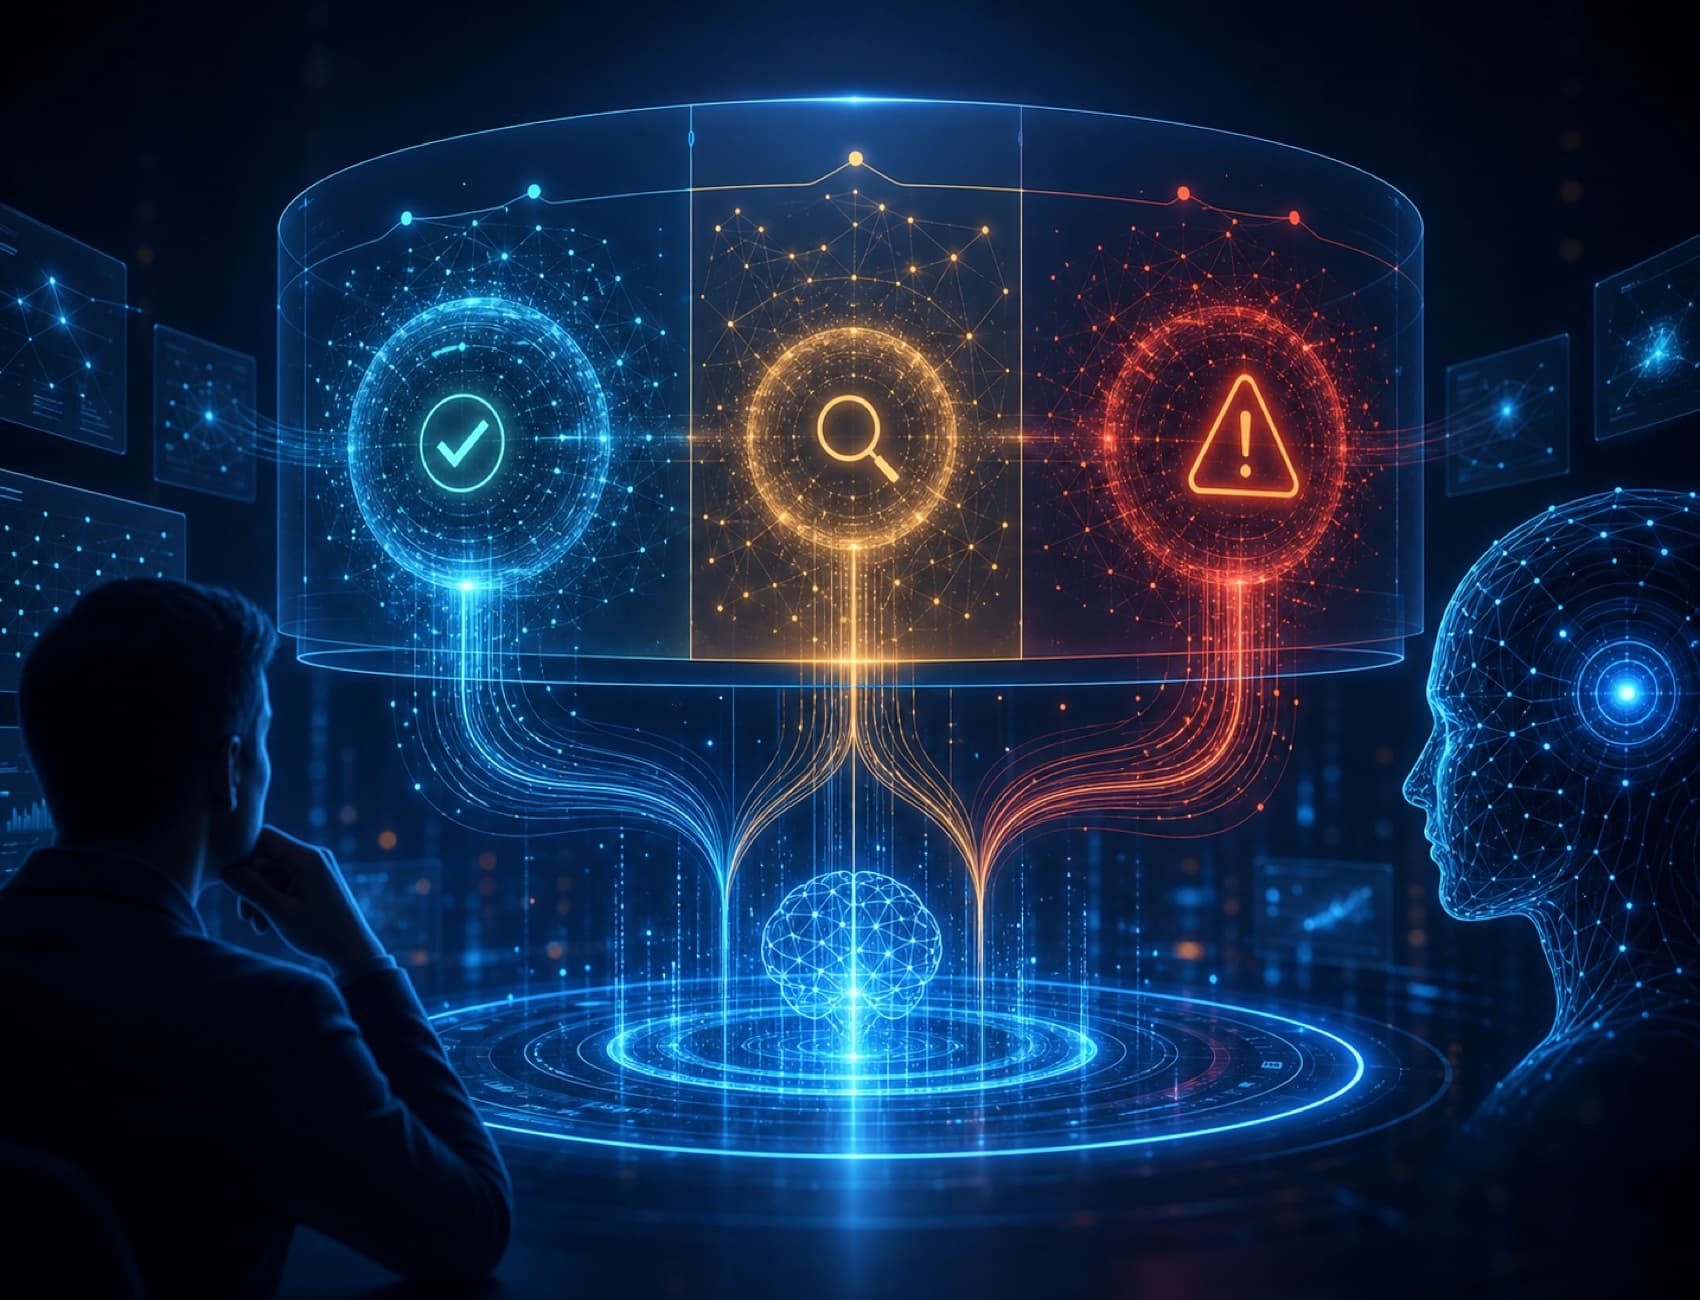
A mature AI system should not treat all outputs equally. It should separate outputs into different action zones:
- High-confidence outputs that can move forward with minimal review.
- Medium-confidence outputs that require human checking.
- Low-confidence outputs that should be blocked, revised, or escalated.
This is where practical AI maturity begins.
Why confidence thresholds matter
They prevent silent overreach
AI systems often create risk quietly.
The output looks fluent. The structure looks professional. The explanation sounds reasonable. Because of that, people may assume the answer is more reliable than it is.
This is dangerous because fluency is not the same as confidence.
A system can sound clear while being uncertain. It can produce a polished answer from weak evidence. It can recommend an action without understanding the full business context.
Confidence thresholds force the workflow to ask: is this answer strong enough for the next step?
That question slows down the wrong things and protects the important things.
They make human review more useful
Many organizations add human review as a blanket safety layer.
This sounds responsible, but it can become inefficient. If every AI output requires the same level of review, humans become overloaded. When reviewers are overloaded, they stop reviewing deeply.
The result is review theater.
Confidence thresholds help teams direct human attention where it matters most. High-risk or low-confidence outputs get deeper review. Routine and high-confidence outputs move faster.
This improves both speed and quality.
The goal is not to remove human judgment. The goal is to use human judgment where it has the most value.
They create learning loops
An AI workflow should improve over time.
But improvement requires knowing where the system was uncertain, where humans corrected it, and where the output failed downstream.
Confidence thresholds create data for learning.
Teams can ask:
- Which tasks often fall into low-confidence zones?
- Which categories require repeated human correction?
- Which prompts, data sources, or workflow steps create uncertainty?
- Which outputs were approved but later proved weak?
This turns AI adoption from experimentation into system development.
Without thresholds, mistakes become isolated events. With thresholds, mistakes become signals.
A practical framework for confidence thresholds
Teams do not need a complex governance model to begin. They need a clear operating standard.
1. Classify workflow risk
Start by defining the risk level of each AI-assisted task.
Low-risk tasks may include internal brainstorming, first-draft ideation, note cleanup, or formatting.
Medium-risk tasks may include customer-facing drafts, campaign recommendations, sales enablement materials, or internal analysis.
High-risk tasks may include pricing decisions, legal claims, compliance content, HR decisions, financial advice, medical information, brand statements, and strategic commitments.
The higher the risk, the stricter the threshold.
2. Define evidence requirements
Confidence should not be based only on how convincing the answer sounds.
It should be based on evidence.
For each workflow, define what the AI output must include before it can move forward:
- source references or retrieved context
- reasoning summary
- uncertainty flags
- missing information
- assumptions
- comparison criteria
- recommended next step
This makes the output easier to evaluate.
3. Create action zones
Every workflow should define what happens at each confidence level.
For example:
- Green: output can be used or lightly edited.
- Yellow: output requires human review before use.
- Red: output must be revised, escalated, or blocked.
The labels are less important than the behavior. The system must know what each zone means.
4. Track corrections
Human review should not disappear after the reviewer approves or edits the output.
Corrections should feed back into the system.
If humans keep fixing the same issue, the workflow has a design problem. It may need better context, better retrieval, clearer prompts, stronger examples, narrower task boundaries, or a different escalation rule.
This is how AI systems become more reliable without pretending to be perfect.
The strategic implication
AI maturity is not measured only by how impressive the model is.
It is measured by how clearly the organization knows when to trust, when to check, and when to stop.
That is a leadership issue as much as a technical issue.
When teams deploy AI without confidence thresholds, they outsource judgment to the appearance of intelligence. When they design thresholds clearly, they turn AI into a disciplined operating layer.
The future of AI adoption will not belong to teams that automate the most.
It will belong to teams that know exactly where automation should end and accountability should begin.
Key Takeaways
- Better AI outputs do not automatically create reliable AI workflows.
- Confidence thresholds define when AI work can move forward, when it needs review, and when it must escalate.
- Human review becomes more valuable when attention is directed toward uncertain or high-risk outputs.
- AI systems improve faster when uncertainty, correction, and escalation are tracked as workflow signals.
- Practical AI maturity depends on trust boundaries, not just model capability.
FAQ
What is a confidence threshold in an AI workflow?
A confidence threshold is a defined standard for deciding whether an AI output is good enough to use, needs human review, or should be blocked or escalated.
Why are confidence thresholds important?
They prevent teams from treating all AI outputs as equally reliable. This protects decision quality, brand trust, compliance, and operational accountability.
Can confidence thresholds be automated?
Some parts can be automated, such as scoring, source checks, missing-information flags, or routing rules. But the standard itself should be designed by humans based on risk, context, and business judgment.
Do small teams need this?
Yes. Small teams may not need a complex governance system, but they still need simple rules for when AI output can be trusted and when it requires review.