AI reliability is often discussed as if it is mainly a model problem.
If the model becomes more capable, the output will become more accurate. If the context window becomes larger, the answer will become more complete. If the benchmark score improves, the workflow will become safer.
These improvements matter.
But they do not solve the deeper issue. AI becomes reliable in real work only when model capability is surrounded by operating discipline: clear inputs, defined roles, review standards, escalation rules, failure memory, and human accountability.
AI reliability needs operating discipline, not only better models.
The Model-Centered Assumption
The model-centered assumption is understandable. Most visible AI progress comes from better models. They reason better, write better, summarize better, code better, and handle more complex instructions.
So teams naturally assume that reliability will arrive through model upgrades.
But real workflows are not benchmark environments. They contain messy instructions, incomplete data, shifting priorities, unclear owners, political pressure, customer consequences, and hidden assumptions.
In that environment, even a strong model can produce weak outcomes if the surrounding system is poorly designed.
A better model can reduce some errors. It cannot compensate for unclear operating standards.
Reliability Is a System Property
Reliability is not just whether AI can answer correctly once. It is whether the workflow can produce dependable outcomes repeatedly under changing conditions.
That requires more than intelligence.
It requires knowing what information enters the system, who validates it, what standards define acceptable output, what uncertainty must be surfaced, what failure patterns are recorded, and who remains accountable when decisions affect people, money, brand, or learning.
The model is one component.
The operating system around the model determines whether capability becomes dependable performance.
Where AI Reliability Usually Breaks
AI reliability often breaks at the input layer. Teams give the model incomplete context, vague objectives, or conflicting instructions, then blame the output.
It breaks at the ownership layer. No one is clearly responsible for reviewing the answer, updating the workflow, or correcting repeated failure patterns.
It breaks at the evaluation layer. Teams judge output by whether it sounds useful instead of whether it meets a defined standard.
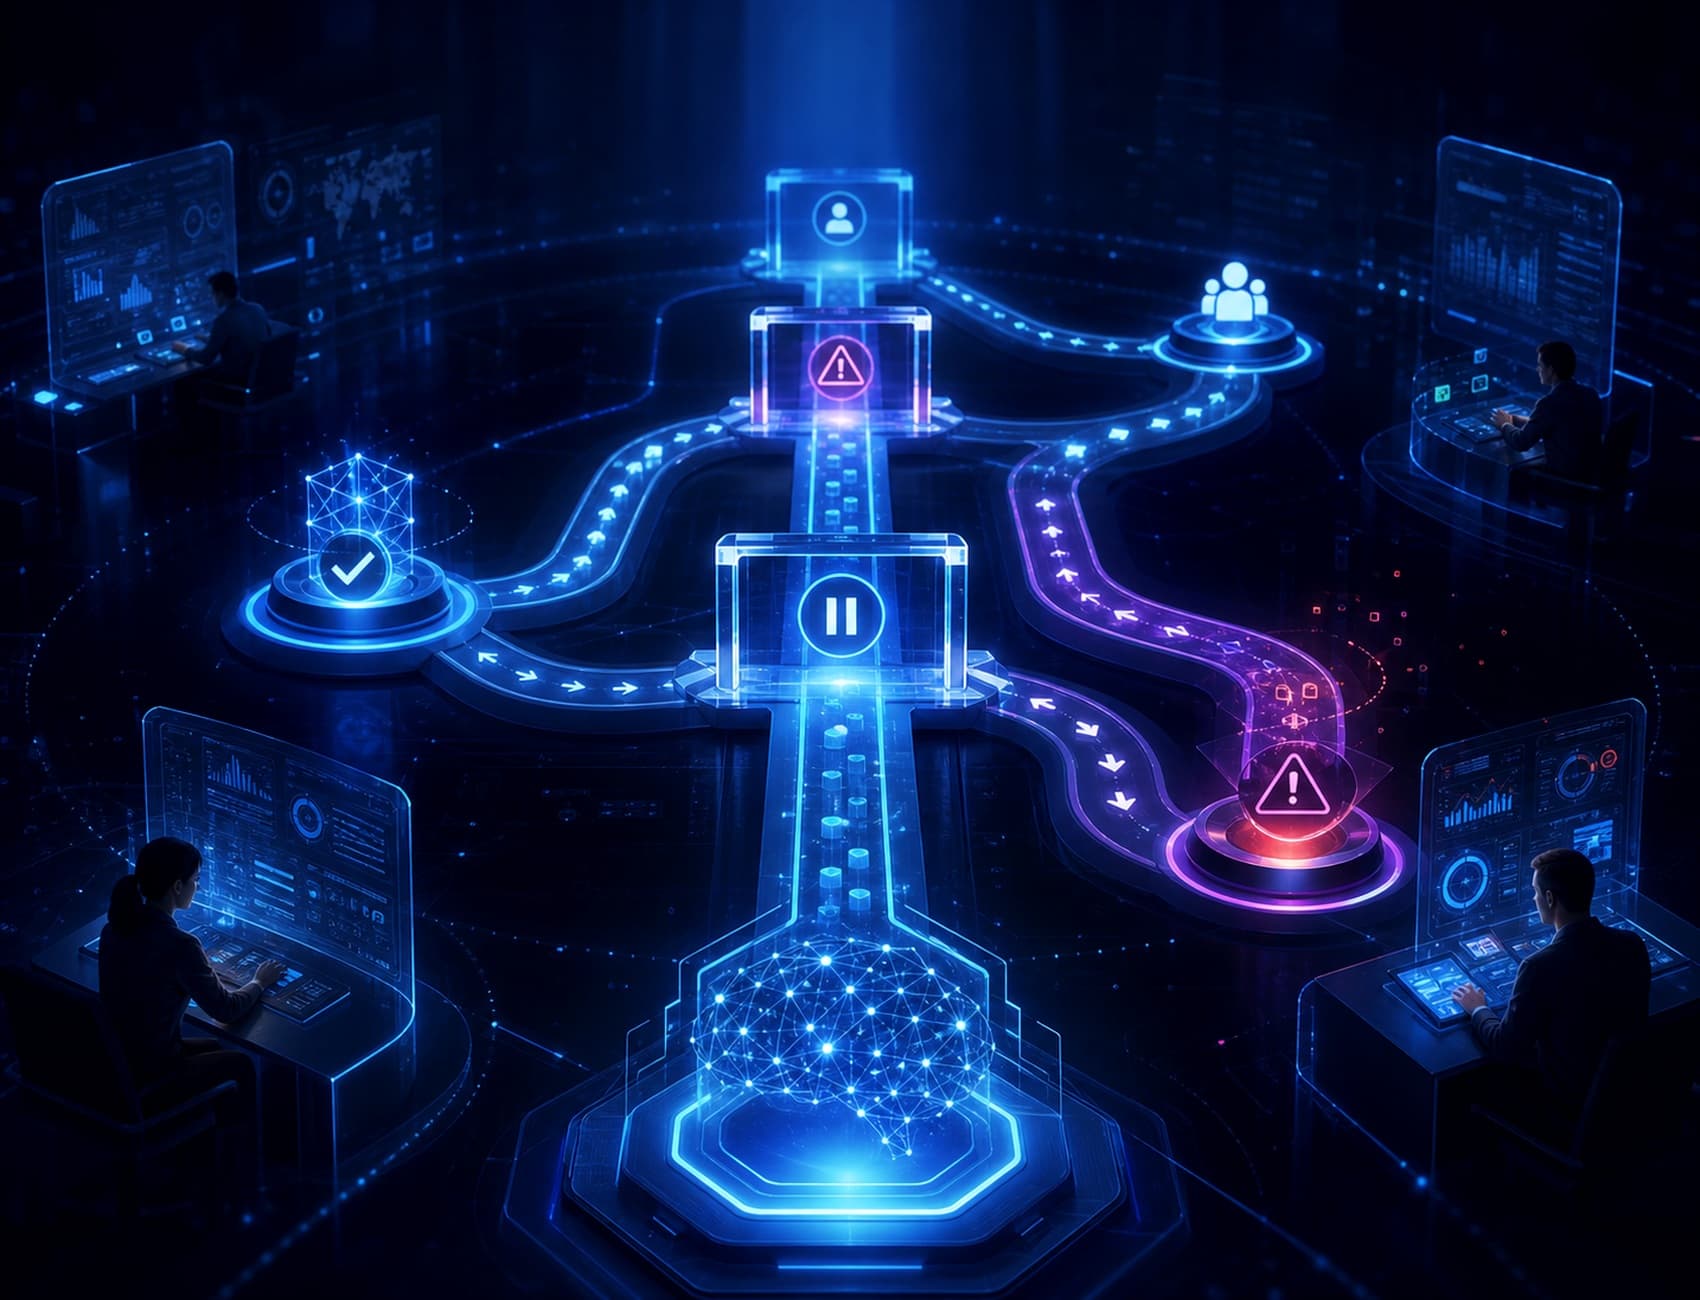
It breaks at the escalation layer. The system has no rule for when AI should pause, ask for help, or route the task to a human.
It breaks at the memory layer. Mistakes happen, get fixed manually, and then disappear. The next workflow repeats the same weakness.
These are not model problems alone. They are operating discipline problems.
The Discipline AI Workflows Need
The first discipline is input discipline. The team must define what context is required before AI can produce useful work. Good inputs are not decoration; they are reliability infrastructure.
The second discipline is role discipline. AI should have a clear role in the workflow. Is it drafting, checking, classifying, researching, comparing, or recommending? Confusion about role creates confusion about trust.
The third discipline is review discipline. Output should be evaluated against criteria, not personal impression. A useful review standard asks whether the answer is accurate, complete, relevant, appropriately cautious, and aligned with the purpose of the workflow.
The fourth discipline is escalation discipline. Every serious AI workflow needs rules for uncertainty, high consequence, missing data, or ethical risk.
The fifth discipline is learning discipline. Errors should feed back into prompts, checklists, data quality, review rules, and workflow design.
What Leaders Should Do
Leaders should stop asking only, "Which model should we use?"
They should also ask:
- What decision or workflow is this AI system supporting?
- What context must be present before AI begins?
- What standards define an acceptable output?
- What requires human review?
- What repeated mistakes should be stored and corrected?
- Who owns the workflow when the model is wrong?
These questions move AI adoption from experimentation to operational maturity.
They also prevent a common mistake: treating AI reliability as something purchased from a vendor instead of something built through disciplined workflow design.
Final Thought
Better models will continue to matter.
But the organizations that gain real advantage from AI will not be the ones that wait passively for models to become perfect. They will be the ones that design operating discipline around imperfect but powerful systems.
AI reliability is not a feature that appears automatically.
It is a management capability.
The model creates potential. Operating discipline turns that potential into trust.
Key Takeaways
- AI reliability depends on the workflow around the model, not only the model itself.
- Many failures come from unclear inputs, weak ownership, missing standards, and poor escalation rules.
- Leaders should treat reliability as an operating capability that must be designed, reviewed, and improved.
FAQ
Does a better model reduce reliability problems?
Yes, but only partly. Better models can improve output quality, but they do not automatically define context, accountability, review standards, or escalation rules.
What is the first step toward reliable AI workflows?
Start by defining the workflow role of AI, the required input context, and the review standard for acceptable output.
Why is failure memory important?
Failure memory prevents teams from correcting the same AI mistakes manually again and again. It turns errors into workflow improvement.