AI agents are moving from answering questions to carrying out work. That change sounds incremental, but operationally it is profound.
An assistant can produce a weak answer and wait for a person to notice. An agent can search across systems, modify a file, update a record, contact another service, or move a workflow forward before anyone recognizes that its reasoning was incomplete.
The real issue is no longer prompt quality alone. It is whether the organization can see what the agent did, why it did it, where it became uncertain, and what happened afterward.
As execution expands, observability becomes part of AI capability.
The Prompt Is Only the Front Door
Many teams still treat agent reliability as a prompt-engineering problem. They add more instructions, examples, restrictions, and formatting rules. This can improve behavior, but it does not create operational control.
A production agent is influenced by more than its initial prompt:
- the context retrieved at runtime;
- the tools and permissions available;
- the state of external systems;
- the sequence of intermediate decisions;
- the quality of human approvals;
- and the feedback captured after execution.
A well-written prompt cannot guarantee that a customer record is current, an API behaves as expected, or an exception is routed to the right person. The prompt defines intent. The operating system around the agent determines whether that intent survives contact with reality.
This distinction matters because organizations are rapidly asking AI to do, not merely advise. OpenAI's 2026 enterprise research describes this movement from assistance to execution and reports that agentic use is spreading across functions including legal, sales, recruiting, and marketing. The more work agents perform, the less sufficient output inspection becomes.
What Operational Observability Means
Observability is not the same as storing every line of a technical log. More data does not automatically create more understanding.
Operational observability means being able to reconstruct the meaningful path from request to outcome.
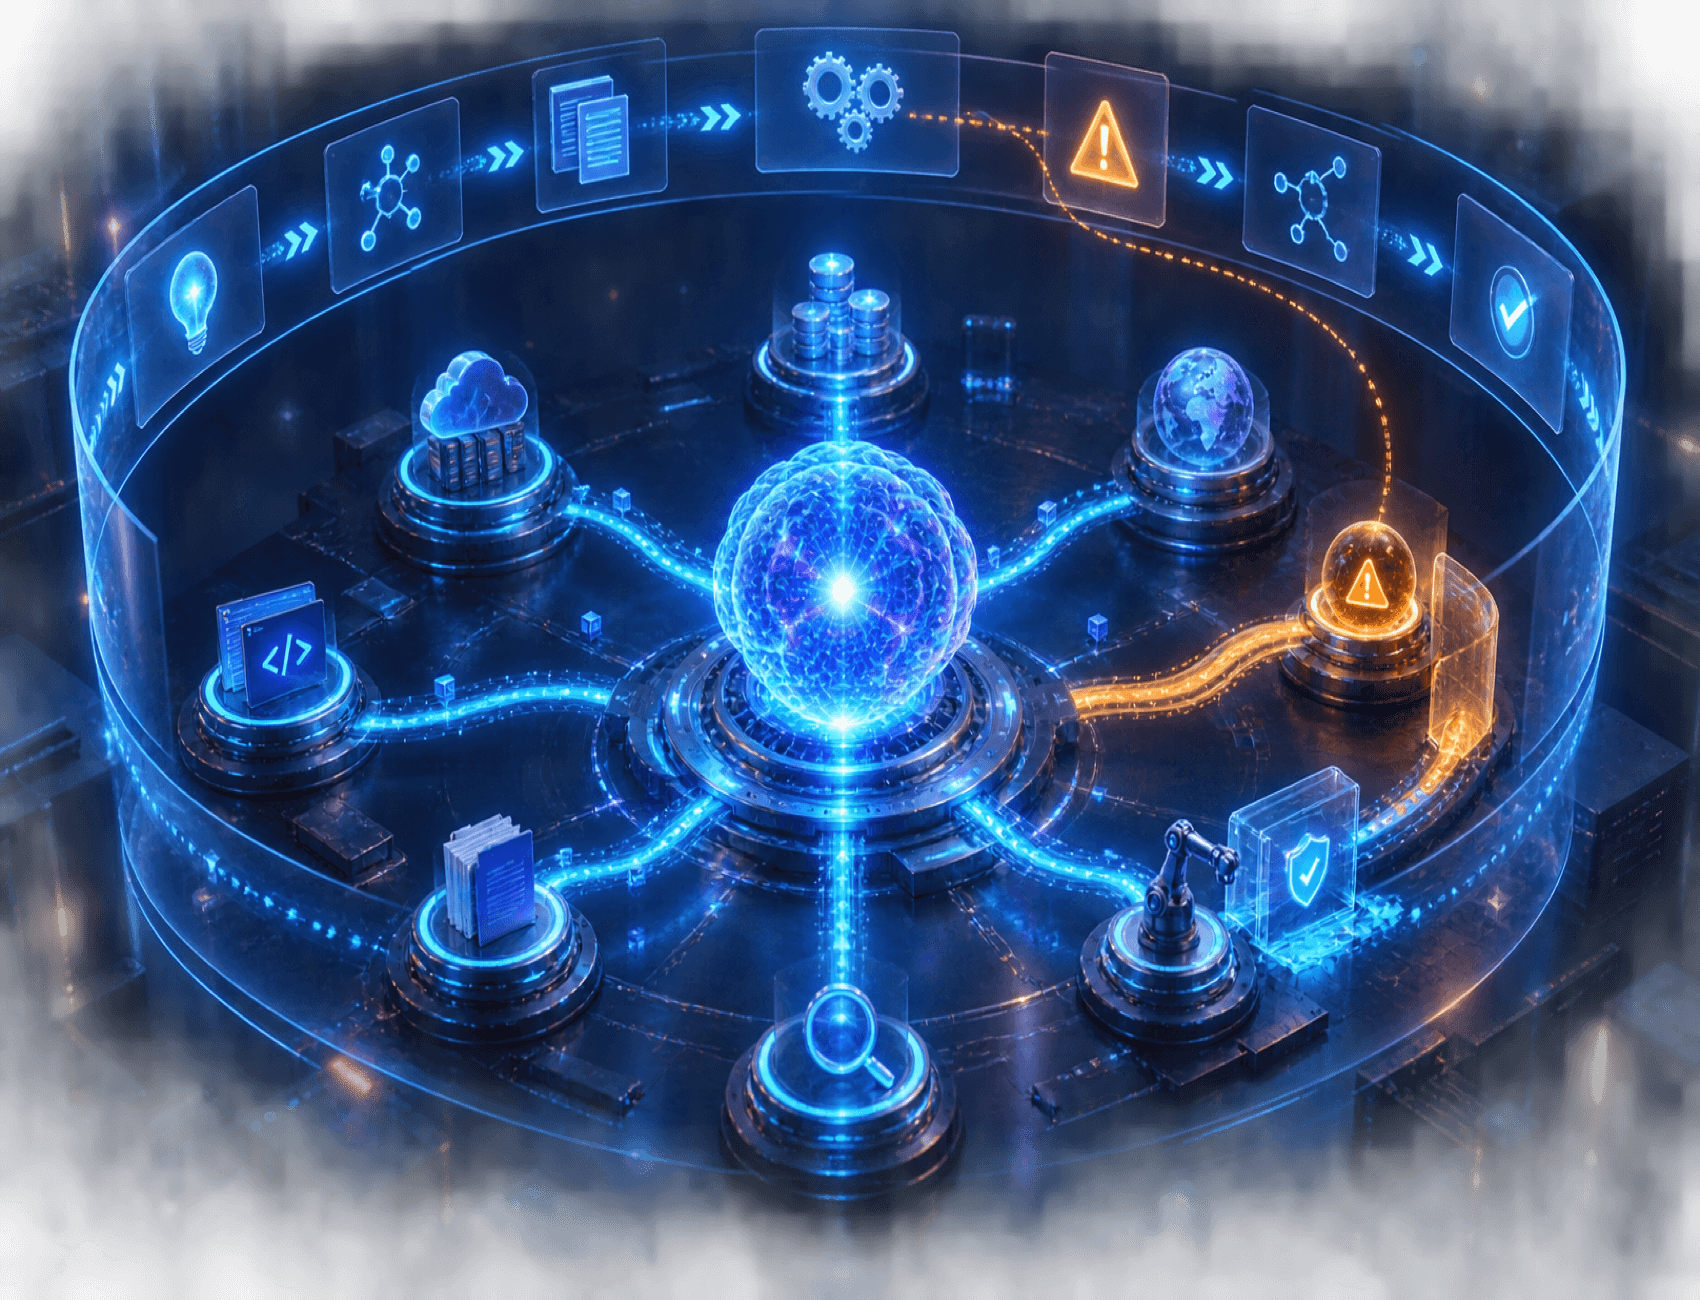
For an AI agent, that path usually includes five layers.
1. Intent
What job was the agent asked to complete? What constraints, success criteria, and boundaries applied?
If intent is vague, later evaluation becomes subjective. A team cannot reliably determine whether an agent succeeded if it never defined what success meant.
2. Context
What information did the agent use? Which source, version, timestamp, or customer state informed its decision?
An answer can appear reasonable while being based on stale or incomplete context. Context provenance makes that failure diagnosable.
3. Action
Which tools did the agent call? What data did it read or change? Which permissions were exercised?
This is the difference between knowing that an agent completed a task and knowing how the task was completed.
4. Exception
Where did confidence fall? Which policy conflict, missing field, failed tool call, or ambiguous instruction appeared?
Exceptions are not noise. They are often the most valuable signals for improving workflow design.
5. Outcome
Did the action produce the intended business result? Was it later corrected, reversed, escalated, accepted, or ignored?
Without outcome feedback, an agent can optimize for task completion while repeatedly creating downstream work.
Why Output Evaluation Is Not Enough
Traditional AI evaluation often focuses on the final response. That approach works when the model's main product is text. It becomes incomplete when the agent changes the world around it.
Two agents can generate the same final message while taking very different operational paths. One may use an approved source and remain within its permissions. The other may rely on outdated data, retry a failed action several times, and require a hidden manual correction.
From the user's perspective, both tasks may look complete. From the organization's perspective, they carry very different risk and cost.
The unit of evaluation must therefore expand from answer quality to execution quality.
Execution quality asks:
- Was the correct workflow followed?
- Were the right sources used?
- Did the agent stay within authority?
- Were exceptions surfaced at the right time?
- Did the result reduce or create downstream work?
- Can the decision be reconstructed when challenged?
These questions make AI performance legible to operations, compliance, management, and the people responsible for the outcome.
A Practical Observability Framework
Organizations do not need to monitor everything equally. They need visibility proportional to consequence.
Step 1: Classify actions by reversibility
Reading a document is different from changing a price. Drafting an email is different from sending it. Recommend stronger monitoring as actions become harder to reverse or more visible to customers.
Step 2: Define the minimum decision trace
For each workflow, specify what must be captured: objective, sources, tool calls, approvals, exceptions, and final state. Avoid collecting data without a clear review purpose.
Step 3: Create exception categories
Do not send every anomaly into one queue. Separate missing context, policy ambiguity, permission failure, low confidence, tool failure, and outcome disagreement. Different exceptions require different owners.
Step 4: Connect traces to business outcomes
Agent telemetry should not live only inside a technical dashboard. Link it to resolution time, rework, customer satisfaction, error rates, conversion quality, or another meaningful operational result.
Step 5: Review patterns, not only incidents
An individual failure may look random. Repeated exceptions reveal structural weaknesses: a poor source of truth, an unclear policy, an overly broad permission, or a task that should not yet be automated.
Observability Is a Learning System
The deepest value of observability is not surveillance. It is institutional learning.
When teams can see where agents hesitate, fail, or create rework, they can improve more than the model. They can improve the process, the data, the permission structure, the escalation path, and the definition of the job itself.
This is why mature AI adoption often exposes weaknesses that already existed. The agent does not create every ambiguity. It makes operational ambiguity visible at machine speed.
Organizations that treat these signals as isolated AI errors will keep patching prompts. Organizations that treat them as evidence about the system will build stronger workflows.
Conclusion
Better models and better prompts will continue to matter. But once AI begins executing work, reliability depends on what the organization can observe and learn.
The future of enterprise AI will not be defined only by agents that can act. It will be defined by systems that can explain action, detect exceptions, connect behavior to outcomes, and improve without losing control.
Execution creates leverage. Observability makes that leverage governable.
Key Takeaways
- Agent reliability is an operational system problem, not only a prompt problem.
- Teams need visibility into intent, context, actions, exceptions, and outcomes.
- Evaluation must expand from answer quality to execution quality.
- Observability should be proportional to the reversibility and consequence of an action.
- The most valuable traces improve the workflow, not merely the model.
FAQ
What is AI agent observability?
It is the ability to understand and reconstruct how an agent moved from a request to an outcome, including the context it used, actions it took, exceptions it encountered, and approvals it received.
Is logging every interaction enough?
No. Raw logs can be extensive but difficult to interpret. Effective observability captures the decisions and events required to evaluate risk, diagnose failure, and improve outcomes.
Which agent actions need the strongest monitoring?
Actions that are difficult to reverse, affect customers, change financial or operational records, exercise broad permissions, or create regulatory and reputational consequences.