AI can increase the speed and volume of organizational output. It can also increase the amount of work that must be reviewed.
This second effect receives far less attention.
When employees use AI to produce analyses, proposals, messages, code, reports, and decisions, the cost of creating a first version falls. But the cost of verifying accuracy, fit, risk, and accountability does not disappear. In some workflows, it grows.
The deeper leadership challenge is not simply enabling AI use. It is designing a review system that can absorb AI-generated work without exhausting the organization or weakening responsibility.
Production Is Becoming Cheaper Than Verification
Before generative AI, producing a substantial draft often required enough effort that people filtered what they created. They decided which report was worth writing, which analysis deserved attention, and which idea was developed far enough to share.
AI lowers that production threshold. Employees can generate more alternatives, documents, insights, and recommendations in less time.
That creates leverage, but it also removes a natural constraint.
Managers may receive five polished proposals instead of one considered recommendation. Legal teams may review more contracts because drafting is faster. Marketing leaders may face dozens of creative variants. Executives may see more dashboards, summaries, and strategic options than they can meaningfully evaluate.
The bottleneck moves from creation to judgment.
If leadership continues to manage as though production were scarce, review capacity becomes overloaded.
The Review Burden Is Often Hidden
Organizations usually measure AI adoption through usage, time saved, output volume, or task completion. These measures can miss the work transferred downstream.
An employee saves two hours drafting a report, but a manager spends an extra hour checking unsupported claims. A campaign team produces more assets, but brand review becomes a queue. A support agent resolves more cases, but complex errors require senior intervention. A software team generates code faster, but reviewers face larger pull requests and less obvious failure modes.
The system appears more productive at the point of generation while becoming slower at the point of assurance.
This is review debt: the accumulation of verification work created faster than the organization can responsibly process it.
Like technical debt, review debt may remain invisible for a period. Work continues to move. Then errors, delays, decision fatigue, and accountability gaps begin to compound.
Not Every Output Deserves the Same Review
The common response is either to review everything or to trust users to review their own work. Both approaches are incomplete.
Universal review destroys much of the speed AI creates. Unstructured self-review assumes that every employee understands the relevant risks, standards, and limitations.
The better approach is risk-based review architecture.
Review intensity should reflect at least four variables.
Consequence
What happens if the output is wrong? Internal brainstorming and public financial guidance should not follow the same process.
Reversibility
Can the action be easily corrected? A private draft is reversible. A message sent to thousands of customers is not.
Detectability
Will an error become obvious quickly, or can it remain plausible and hidden? Fluent but false analysis is often harder to detect than a visible system failure.
Novelty
Is the task routine and well-defined, or does it involve an unfamiliar context, new policy, or ambiguous judgment?
These variables allow leaders to assign review resources where they create the most value.
A Four-Level Review Architecture
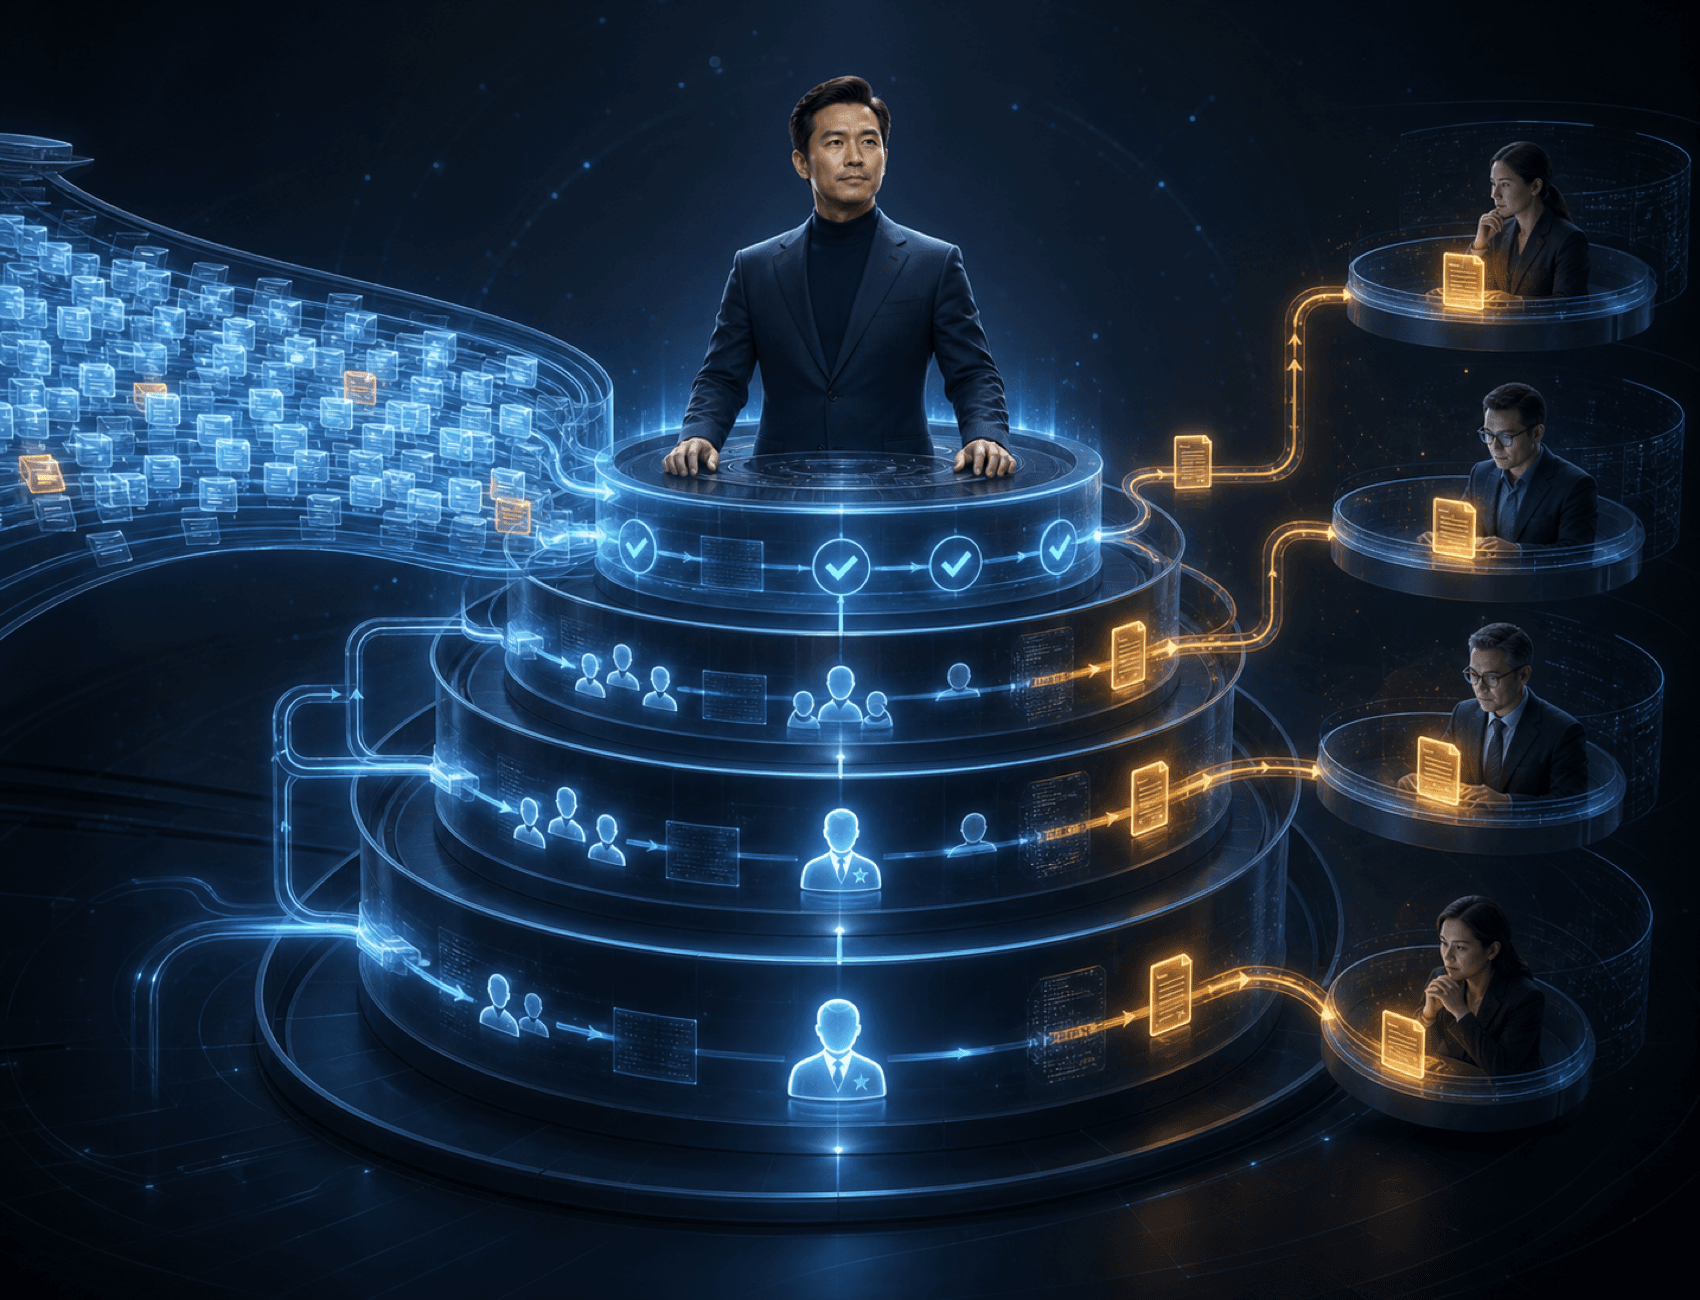
Organizations can translate risk into four practical levels.
Level 1: Self-check
Use for low-consequence, reversible work. The employee follows a simple checklist and remains accountable for the result.
Examples include internal notes, early ideation, or formatting assistance.
Level 2: Peer review
Use when a second perspective can catch factual, contextual, or quality issues without specialist approval.
Examples include routine client materials, analysis drafts, and internal process documents.
Level 3: Expert approval
Use when the output touches legal, financial, medical, security, brand, or other specialized standards.
The expert should review the risky element, not necessarily recreate the entire task.
Level 4: Leadership decision
Use for high-consequence, difficult-to-reverse choices involving strategy, values, resource allocation, public commitments, or accountability across functions.
AI can inform these decisions. It should not obscure who owns them.
Review Must Be Designed Into the Workflow
Review fails when it is added at the end as a vague request to “check this.”
Effective review begins earlier.
Leaders should define:
- what evidence must accompany the output;
- which claims require source verification;
- what AI involvement must be disclosed;
- which thresholds trigger escalation;
- who has authority to approve;
- what turnaround time is reasonable;
- and who owns the final decision.
This turns review from personal caution into organizational infrastructure.
It also improves the quality of delegation. Employees know the boundaries within which they can move quickly and the conditions under which they must slow down.
Do Not Turn Managers Into Human Error Filters
One of the worst possible outcomes of AI adoption is to make every manager the final filter for a rapidly expanding volume of machine-assisted work.
That model does not scale. It produces decision fatigue, superficial approval, and management bottlenecks.
Leaders should reduce unnecessary review through better task design:
- Standardize recurring workflows and acceptance criteria.
- Require evidence and uncertainty to be visible in the first submission.
- Use automated checks for formatting, completeness, policy rules, and known failure patterns.
- Route only genuine exceptions to scarce human expertise.
- Sample low-risk work to monitor quality instead of approving every item.
- Track corrections and rework so the system learns where stronger controls are needed.
The goal is not maximum human inspection. It is the right human judgment at the right point.
Measure Net Capacity, Not Gross Output
AI productivity should be measured across the workflow, not at the person who generated the output.
A useful equation is:
Net capacity created = production time saved − review time added − rework created − coordination cost introduced.
This is not a perfect financial model. It is a leadership discipline.
It forces organizations to ask whether AI is reducing total effort or merely shifting effort to more senior, expensive, or overloaded people.
It also changes adoption priorities. A workflow that saves modest production time but requires little review may create more real capacity than a spectacular demo that generates constant exceptions.
Conclusion
AI does not remove the need for judgment. It changes where judgment becomes scarce.
As production accelerates, leaders must design review capacity with the same seriousness they apply to AI access, training, and tooling. That means classifying risk, defining evidence, routing exceptions, preserving ownership, and measuring the net effect across the whole workflow.
The organization that produces the most AI-assisted work will not necessarily be the most capable. The stronger organization will be the one that can verify what matters without turning every manager into a bottleneck.
Key Takeaways
- AI lowers production cost but can increase verification cost.
- Review debt is hidden work transferred downstream by faster generation.
- Review intensity should reflect consequence, reversibility, detectability, and novelty.
- Leaders need explicit review levels, evidence requirements, and ownership.
- AI productivity should be measured as net capacity across the workflow.
FAQ
What is the AI review burden?
It is the human effort required to verify the accuracy, relevance, safety, and accountability of AI-assisted work after production becomes faster and more abundant.
Should every AI-generated output receive human review?
No. Review should be proportional to risk. Low-consequence and reversible work may need self-checks or sampling, while high-consequence decisions require expert or leadership approval.
How can leaders prevent AI from creating management bottlenecks?
They can standardize acceptance criteria, automate routine checks, require visible evidence, route only exceptions to managers, and measure review time and rework across the workflow.