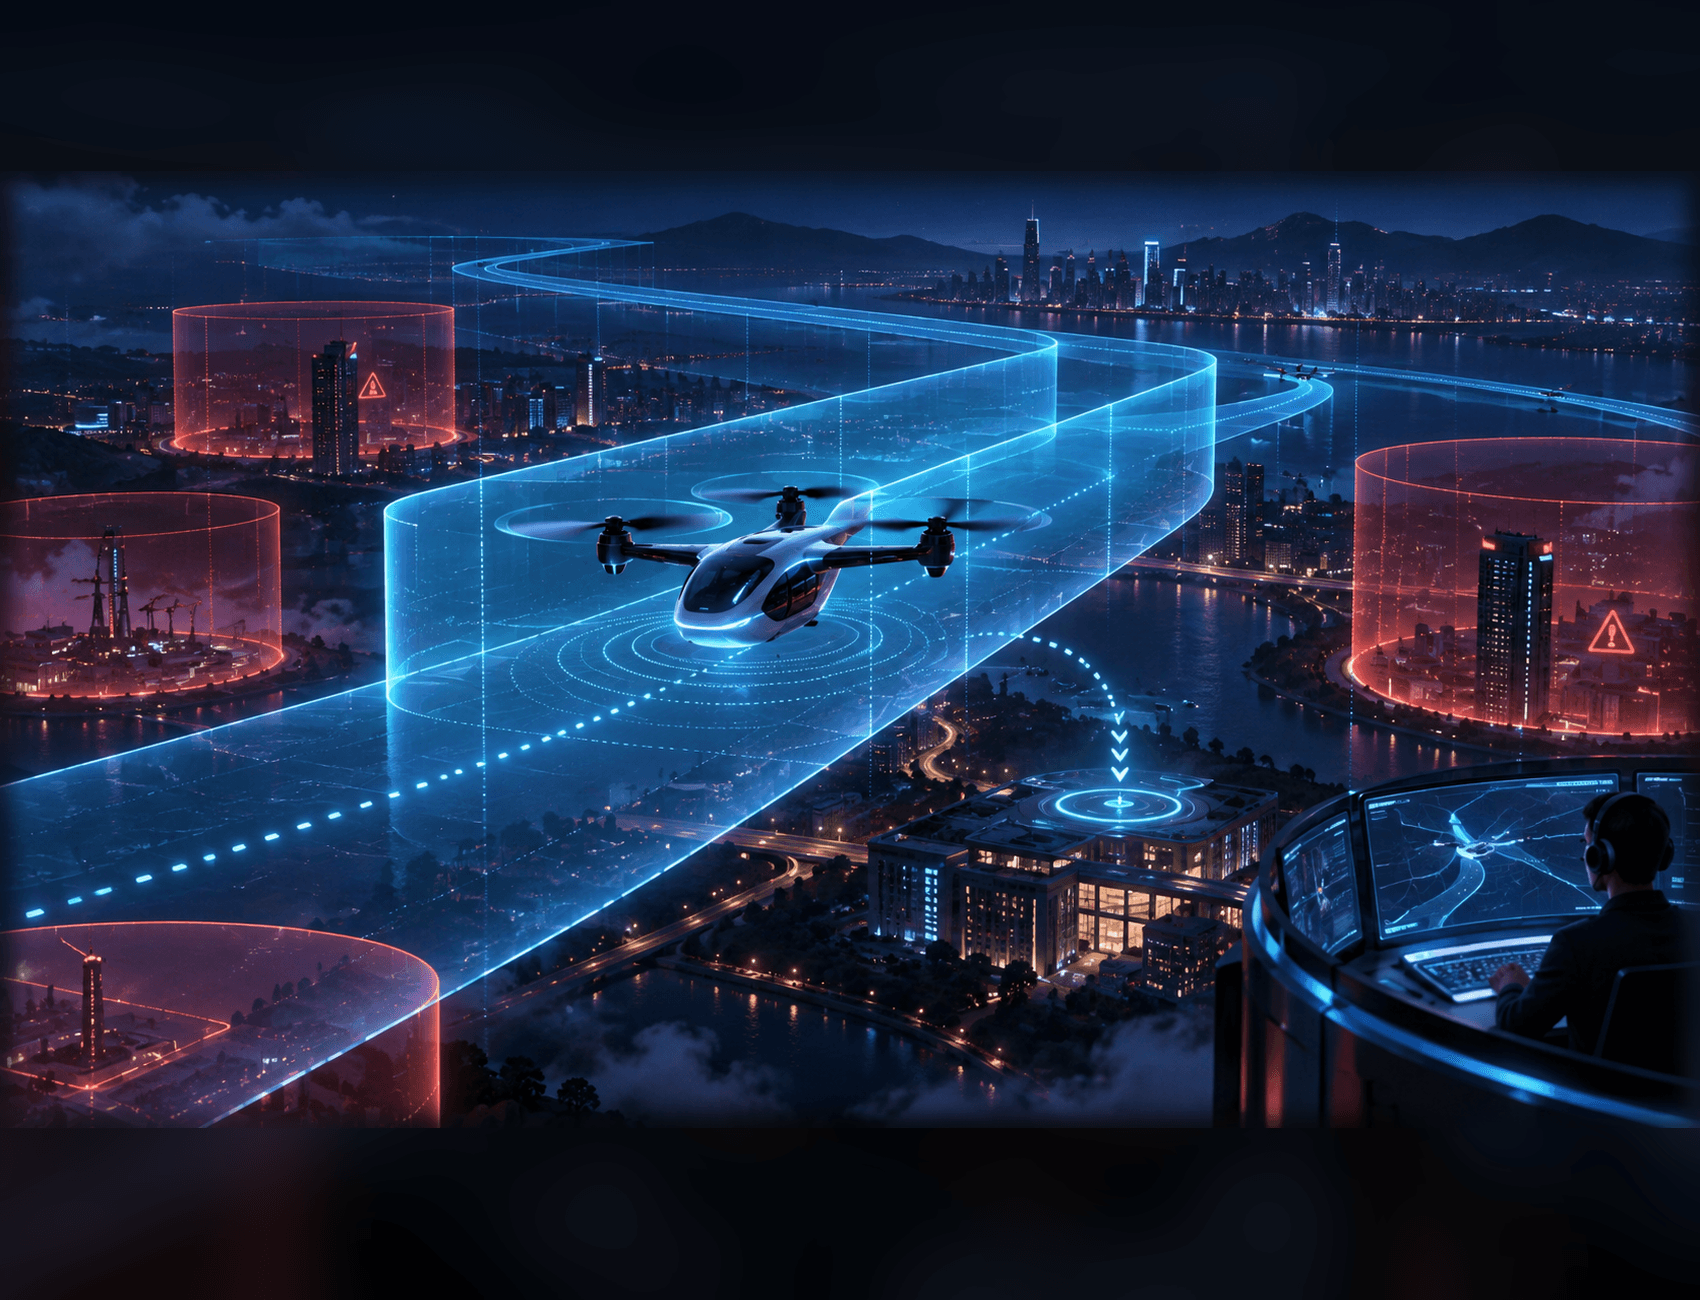
Autonomous AI does not become trustworthy when it completes an impressive demonstration. It becomes trustworthy when the system can operate repeatedly inside clearly defined boundaries, detect when those boundaries are being approached, and transfer control safely when conditions move outside them.
This distinction matters because autonomous systems do not merely recommend. They perceive, decide, and act in environments where weather, infrastructure, human behavior, connectivity, regulation, and physical safety interact.
For these systems, model accuracy is only one layer of performance. The deeper requirement is an **operational envelope**: the explicit set of conditions, responsibilities, fallback mechanisms, evidence thresholds, and escalation rules within which autonomy is permitted.
Without that envelope, a successful demo proves that a system can work. It does not prove that society knows when the system should work, when it should stop, or who remains accountable.
Hanoi's flying-taxi sandbox reveals the real autonomy challenge
On September 28, Government News reported that Hanoi's Department of Science and Technology and Hung Viet Technology had agreed to develop a controlled trial for autonomous EHang passenger and cargo vehicles. The proposed sandbox includes four phases, an operations control center at Hoa Lac Hi-Tech Park, technical training, operating standards, safety rules, and a path toward commercial deployment after evaluation.
The headline is flying taxis. The strategic issue is larger.
Autonomous mobility brings together AI perception, navigation, control systems, infrastructure, data governance, human supervision, emergency response, public trust, and regulatory authority. No single technical test can validate that entire operating system.
The useful question is therefore not, “Can the vehicle fly?” It is, “Under which conditions can the total system operate with evidence, accountability, and recoverability?”
That is the question every autonomous-AI deployment eventually faces, whether the system moves aircraft, vehicles, robots, industrial equipment, or critical digital workflows.
What an operational envelope means
**An operational envelope is the verified range of environmental, technical, organizational, and regulatory conditions within which an autonomous system is allowed to act, together with the controls required when those conditions are violated.**
The concept is broader than a technical specification.
A drone may have limits for wind, visibility, payload, altitude, battery condition, communication quality, and geofenced airspace. But a safe deployment also requires decisions about route authorization, monitoring, incident ownership, maintenance status, passenger eligibility, emergency landing, data retention, and human intervention.
The boundary is therefore not only around the model. It surrounds the complete decision-and-action system.
This is related to [decision locality in edge AI](/blog/edge-ai-decision-locality). Some decisions must remain close to the device because latency matters. Others must be escalated because context, authority, or risk exceeds what the local system should resolve. Operational boundaries determine which is which.
Why demo performance is misleading
Demos remove variation
Demonstrations are usually designed around known routes, prepared infrastructure, selected participants, favorable conditions, and visible technical support. Real operations introduce variation that is difficult to stage completely.
Weather changes. Sensors degrade. Maps become stale. Communication becomes intermittent. People behave unexpectedly. Maintenance quality varies across time. Operators develop shortcuts. Commercial pressure expands use beyond the original design.
A demonstration can show capability under selected conditions. An operational envelope must describe capability across expected variation.
Demos hide organizational dependencies
Autonomy is often presented as independence from people. In practice, it depends on a larger human system.
Someone validates the route. Someone reviews abnormal events. Someone maintains the equipment. Someone updates software. Someone responds when connectivity fails. Someone decides whether the incident is technical, operational, or regulatory.
If those roles are undefined, the autonomy is not mature. It is supported by invisible manual work.
Demos reward completion, not safe refusal
The most convincing moment in a demonstration is successful task completion. In real deployment, a safe system must sometimes refuse, delay, reroute, degrade gracefully, or return control to a human.
This means refusal quality is part of system quality.
An autonomous vehicle that completes more trips by operating beyond safe limits may look productive until the first serious incident. A mature system optimizes successful operation **within evidence-backed boundaries**, not maximum autonomy at any cost.
Demos do not establish public legitimacy
People evaluate physical autonomy differently from a software assistant. The consequences are visible, shared, and sometimes involuntary. A citizen may be affected by an autonomous system without choosing to use it.
Public legitimacy therefore requires more than technical certification. It requires clarity about where the system operates, what data it collects, how incidents are handled, who can stop it, and how learning from the trial changes the next stage.
Build the boundary before expanding the capability
1. Define the operating domain
Specify the conditions under which the system may act:
- location and route;
- time window;
- weather and visibility;
- traffic or crowd conditions;
- infrastructure readiness;
- communication quality;
- payload or passenger limits;
- approved system configuration.
Do not treat these as temporary constraints to be quietly relaxed. Each boundary should have an owner, evidence threshold, monitoring method, and approval path for expansion.
2. Map the consequence of error
Not all errors carry the same cost. A delayed delivery, an incorrect route choice, a failed sensor reading, and a loss of control require different safeguards.
Teams should model the consequences of false positives, false negatives, uncertainty, system silence, and unsafe action. High-consequence decisions need stronger redundancy, narrower authority, and earlier human escalation.
This is why [data zoning for enterprise AI](/blog/enterprise-ai-data-zoning) has a physical equivalent. Access and action should expand only when the sensitivity and consequence of the operating context permit it.
3. Design fallback modes as primary architecture
Fallback is not an emergency appendix. It is part of normal system design.
The system should know how to:
- stop safely;
- return to a known state;
- switch to a degraded mode;
- request human review;
- preserve evidence;
- notify affected operators;
- prevent automatic restart after critical failure.
The handoff must be tested under realistic time pressure. A human supervisor who receives an alert without enough context is not a control layer. That person is simply the final recipient of uncertainty.
4. Separate system health from task success
A completed trip does not mean the system was healthy. It may have succeeded while operating with sensor conflicts, excessive manual intervention, unapproved software, unstable communications, or degraded safety margins.
The trial must measure both output and integrity:
- mission completion;
- boundary violations;
- near misses;
- intervention frequency;
- unplanned manual work;
- sensor and communication degradation;
- maintenance deviations;
- time to detect, contain, and learn from anomalies.
5. Create an evidence ladder for expansion
A sandbox should not move directly from pilot to commercial scale. It should progress through an evidence ladder.
One possible sequence is:
- closed-environment technical validation;
- controlled operation without passengers;
- supervised operation with restricted routes and users;
- limited public operation under defined conditions;
- broader commercial operation after independent review.
Each stage should answer a different question and have explicit continue, revise, pause, or stop criteria. This follows the logic of [experimental closure in scientific AI](/blog/scientific-ai-experimental-closure): evidence must connect prediction, action, observation, and system update.
6. Assign authority across the full incident cycle
Autonomous systems often distribute responsibility across manufacturer, software provider, operator, infrastructure owner, regulator, maintenance team, and emergency services.
That distribution becomes dangerous when every actor owns only a component.
The operating model must define who can authorize a mission, override the system, suspend operations, investigate an incident, approve software changes, communicate publicly, compensate affected parties, and authorize restart.
Accountability cannot be reconstructed after failure.
What a useful sandbox should produce
A sandbox should generate more than permission to test. It should produce reusable public and institutional capability.
The outputs should include:
- a documented operating domain;
- a risk and consequence model;
- technical and organizational safety cases;
- incident and near-miss taxonomies;
- monitoring and audit requirements;
- human-supervision protocols;
- maintenance and software-change controls;
- public communication standards;
- training requirements;
- evidence for regulatory refinement.
Commercial success is only one outcome. Even a trial that does not proceed can create value if it reveals boundary conditions early and improves the next generation of infrastructure and regulation.
The strategic advantage is not maximum autonomy
Cities and companies may feel pressure to prove technological ambition through visible deployments. But leadership in autonomous AI will not belong to whoever removes humans fastest.
It will belong to those who learn how to expand autonomy without losing observability, intervention capacity, public legitimacy, or accountability.
The operational envelope is not a restriction on innovation. It is the mechanism that makes responsible expansion possible.
Conclusion
Autonomous AI should not be judged by whether it can complete a controlled demonstration. It should be judged by whether the surrounding system knows the conditions under which autonomy is justified, how those conditions are monitored, and what happens when they fail.
That requires operational boundaries, staged evidence, tested fallback modes, visible accountability, and disciplined authority to stop.
The future of autonomy will not be built by systems that act everywhere. It will be built by systems that understand precisely where they are allowed to act—and institutions mature enough to enforce that boundary.
Key Takeaways
- Demo success proves capability under selected conditions, not operational trustworthiness.
- An operational envelope defines where autonomy is permitted and what happens when conditions move outside it.
- Safe refusal, degraded modes, and human handoff are core performance capabilities.
- Sandboxes should use staged evidence and explicit continue, revise, pause, or stop criteria.
- Accountability must cover authorization, monitoring, incident response, system change, and restart.
FAQ
What is an operational envelope for autonomous AI?
It is the verified set of environmental, technical, organizational, and regulatory conditions within which an autonomous system may act, together with monitoring, fallback, escalation, and accountability controls.
Why is a successful autonomous-system demo not enough?
A demo usually reduces variation and relies on prepared infrastructure and support. Real operations introduce changing weather, degraded sensors, unexpected human behavior, maintenance variation, and organizational pressure.
What should an autonomous-AI sandbox measure?
It should measure mission outcomes, boundary violations, near misses, intervention frequency, system degradation, manual work, incident response, evidence quality, and readiness for the next operating stage.
When should an autonomous system hand control to a human?
Control should be escalated when the system leaves its approved operating domain, uncertainty exceeds defined thresholds, consequences become too high, or system health prevents safe autonomous action.